Atlas Video Gen Evals
Corporate Partner Project | Stanford EE205 | Jan 2026 – Mar 2026
Helped Gruve identify a market entry point in AI inference through stakeholder research, and scoped an MVP dashboard for benchmarking video inference models.
Problem
AI companies building with video models cannot make confident model decisions. Quality, cost, and latency tradeoffs are invisible until they are already in production. And especially in video generation, choosing the wrong model configuration can become expensive.
How We Found It
We ran 30+ stakeholder interviews across AI infrastructure companies, hypoerscalers, and AI-native startups including OpenRouter, Together, Baseten, Google, Sierra, and Descript, looking for where and how to address inference cost challenges.
What We Built
A use case specific video model evaluation tool, using video quality benchmarks from VBench.
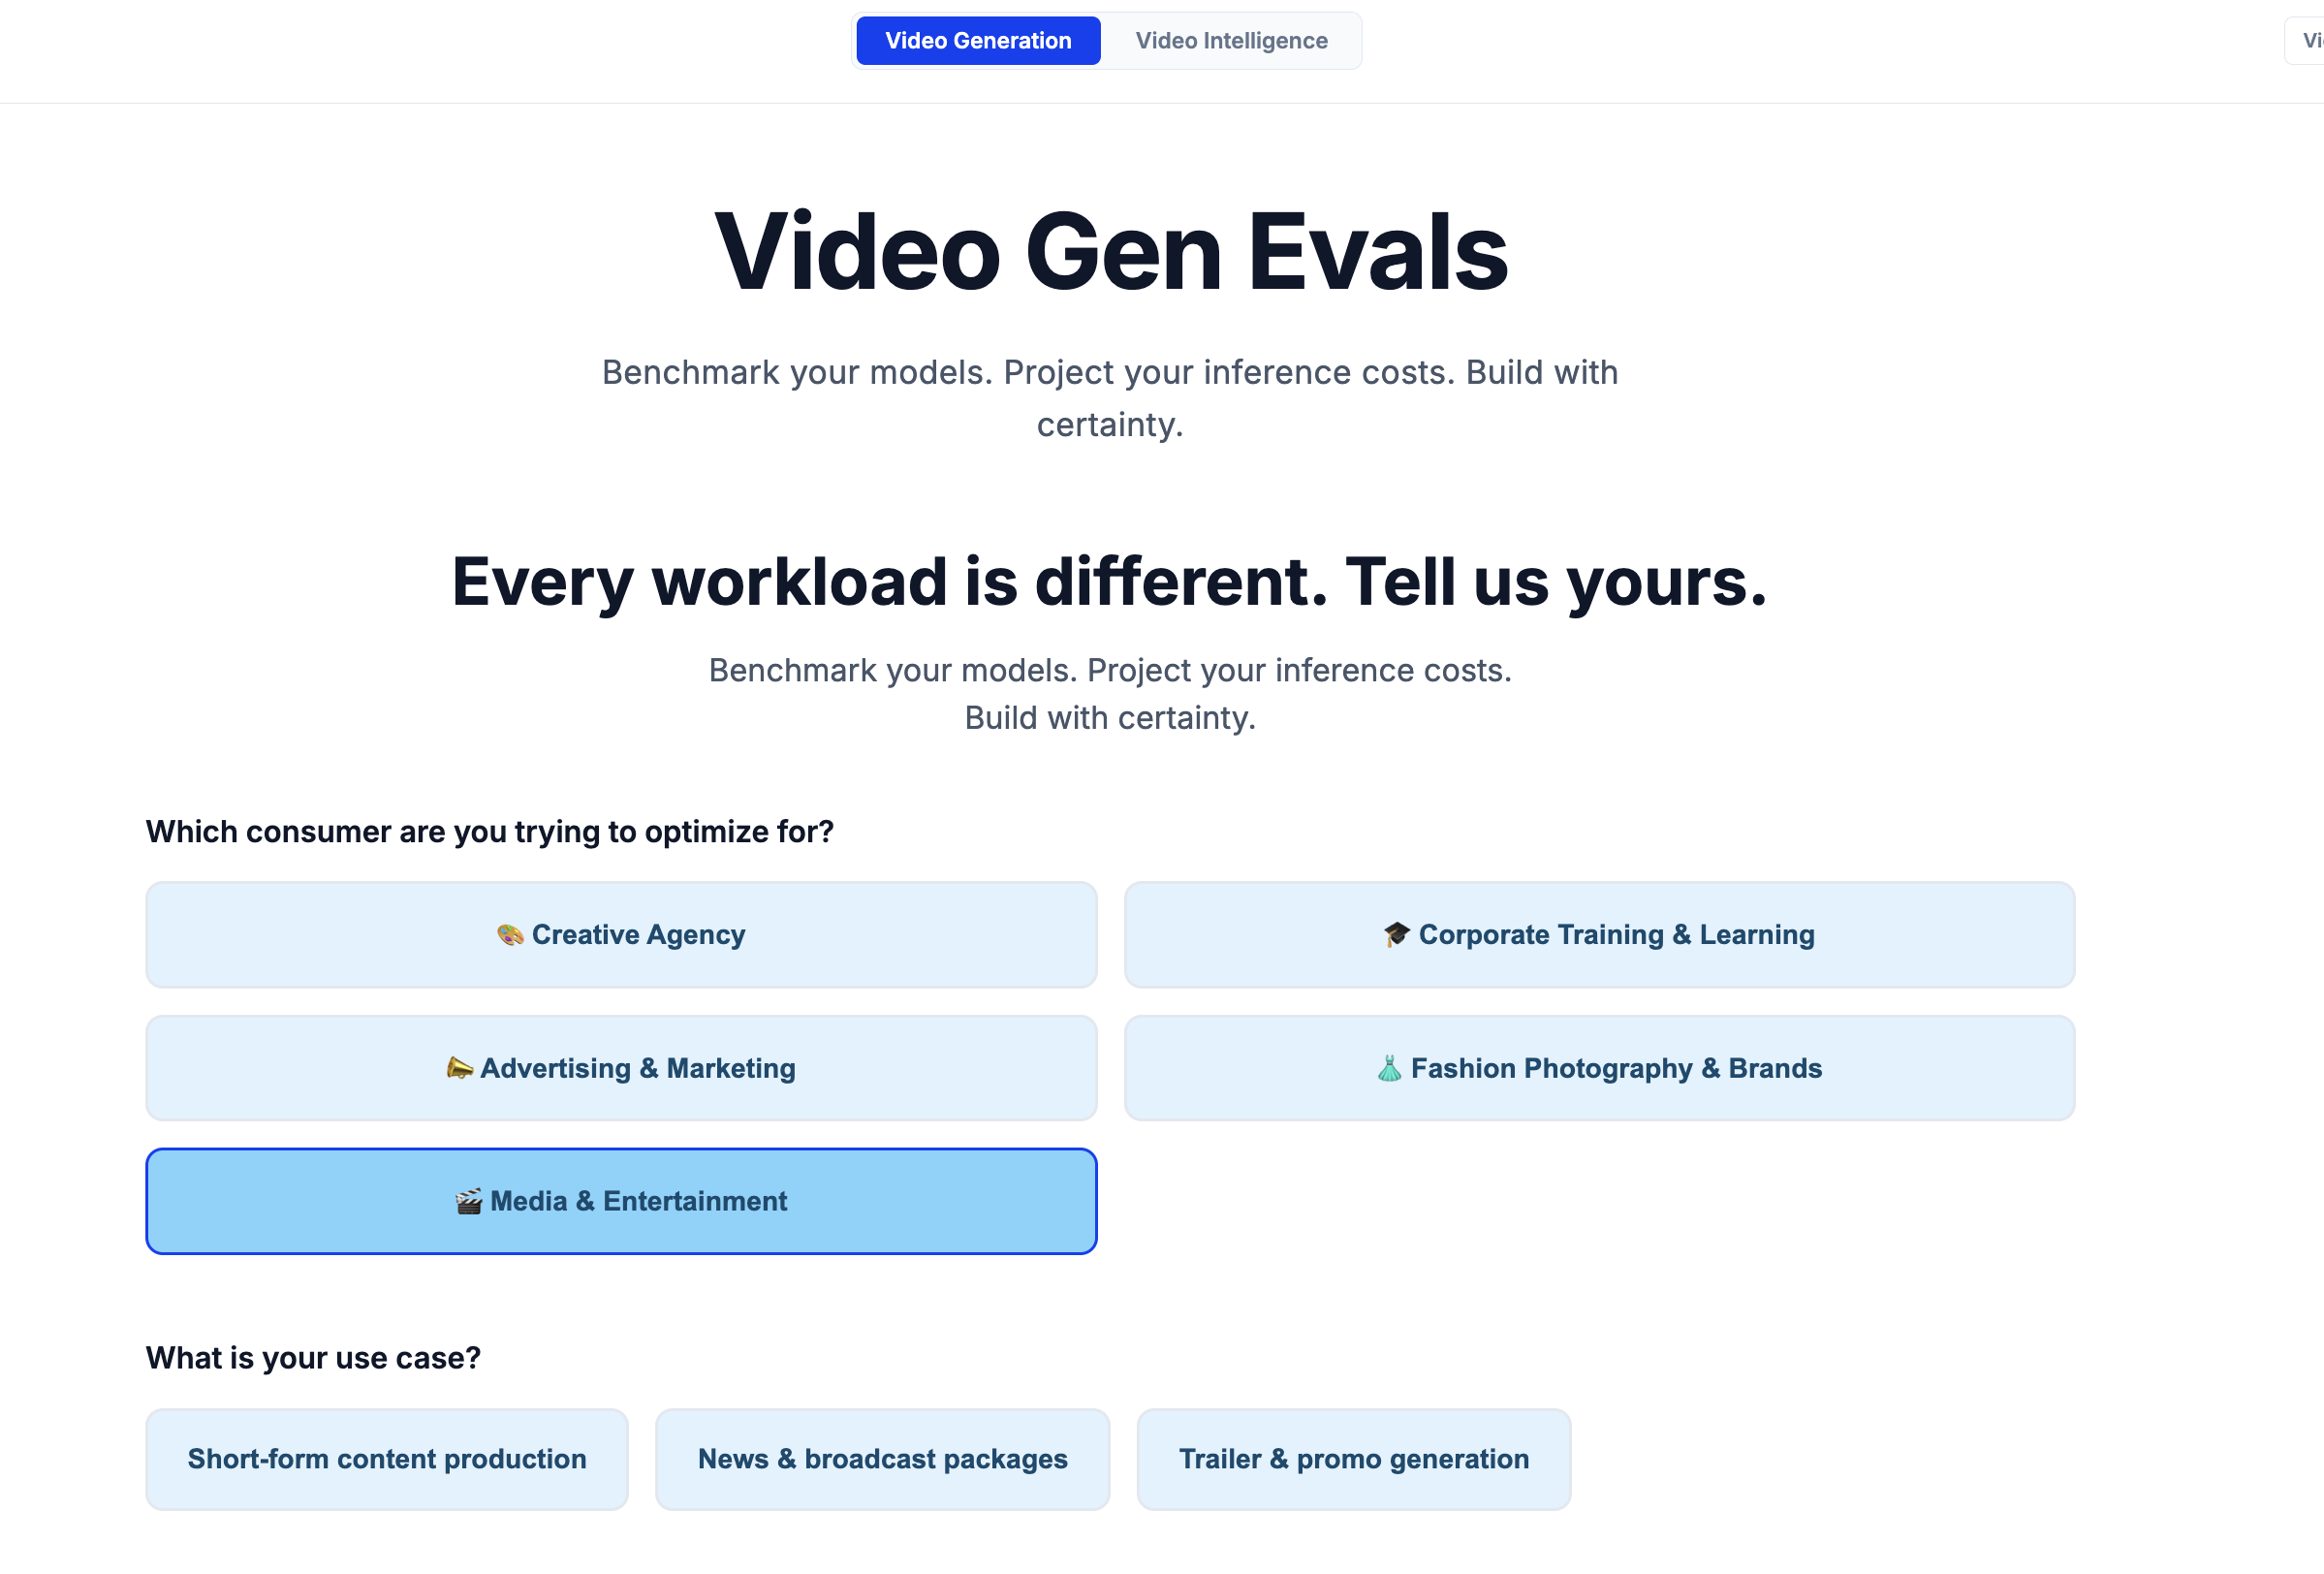
Users start by defining their context, so comparisons are tailored and not generic.
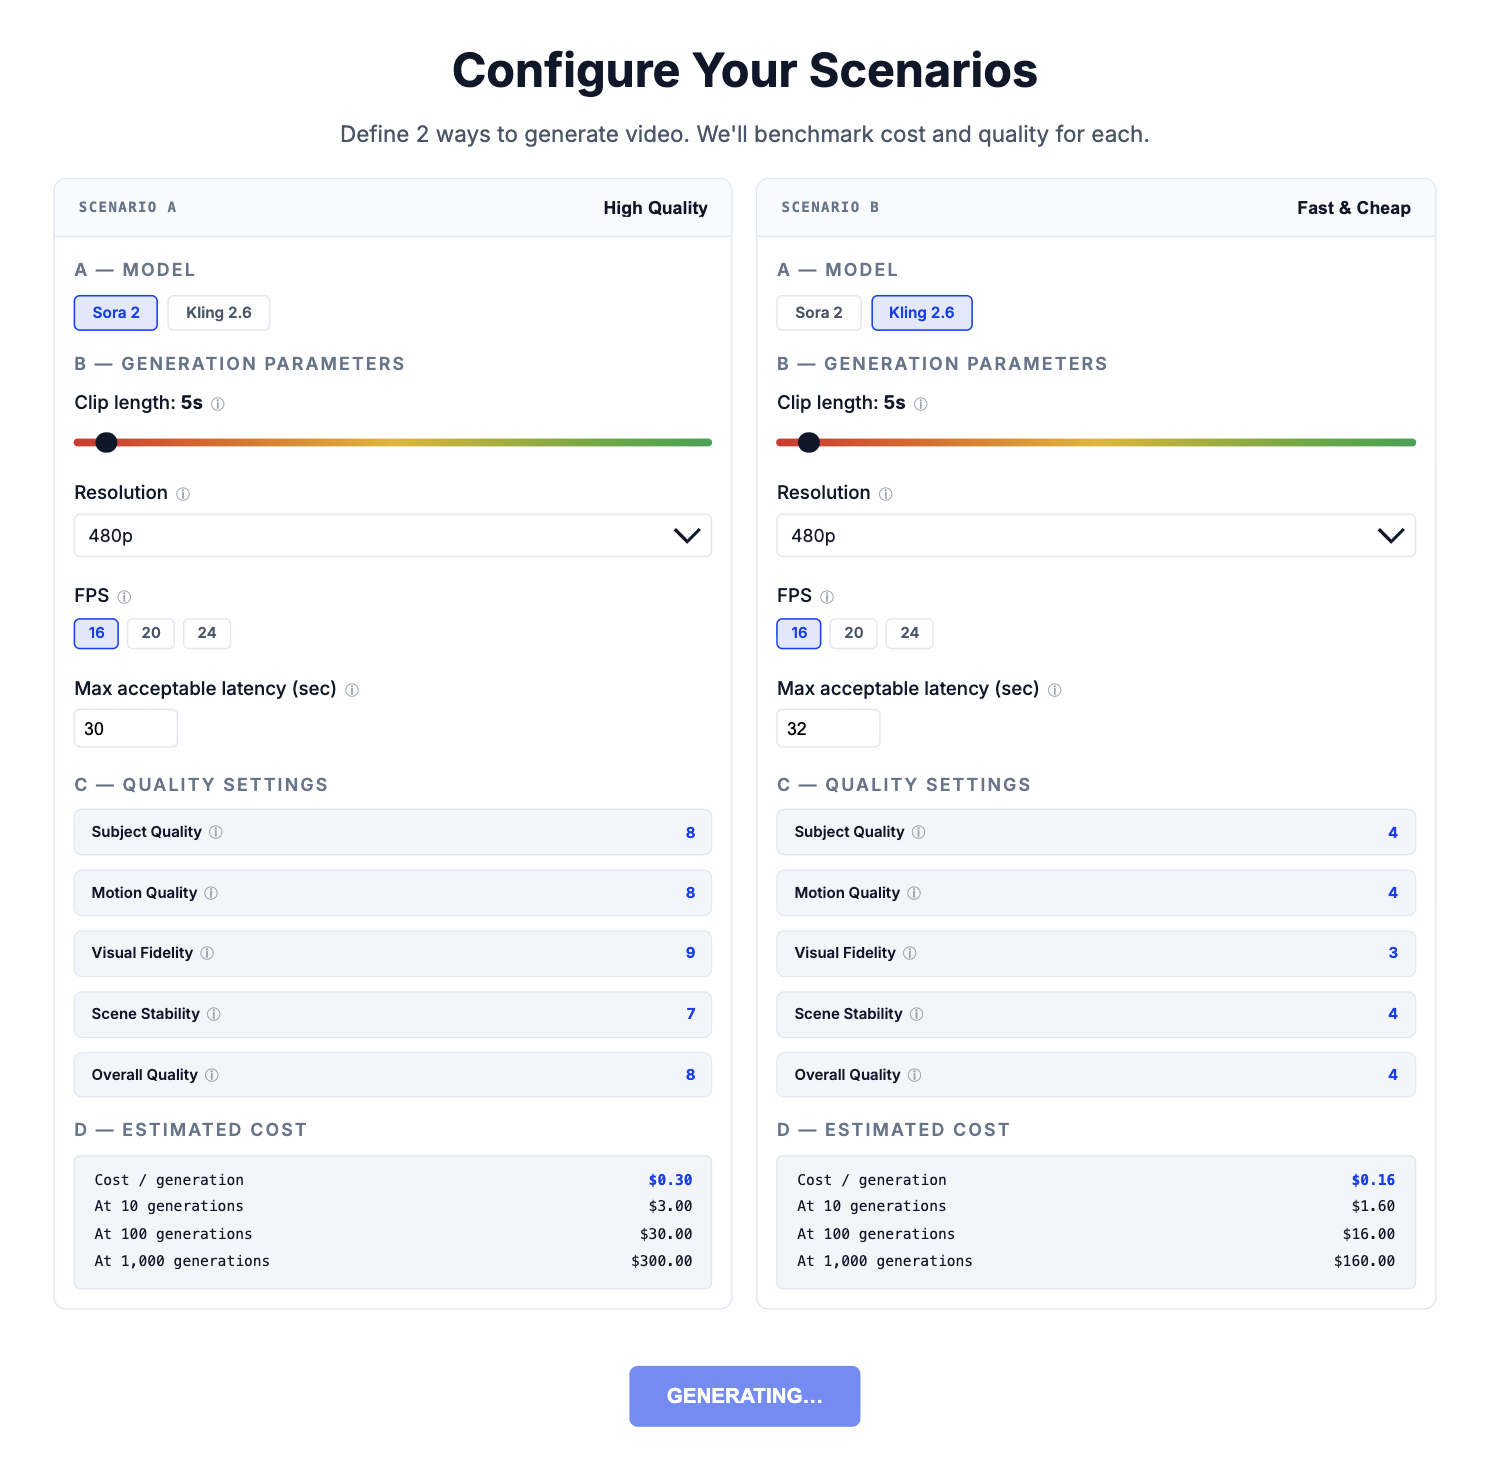
The user can configure two competing scenarios side by side: model, clip length, resolution, FPS, max latency and set minimum quality thresholds with live cost estimates before running anything.
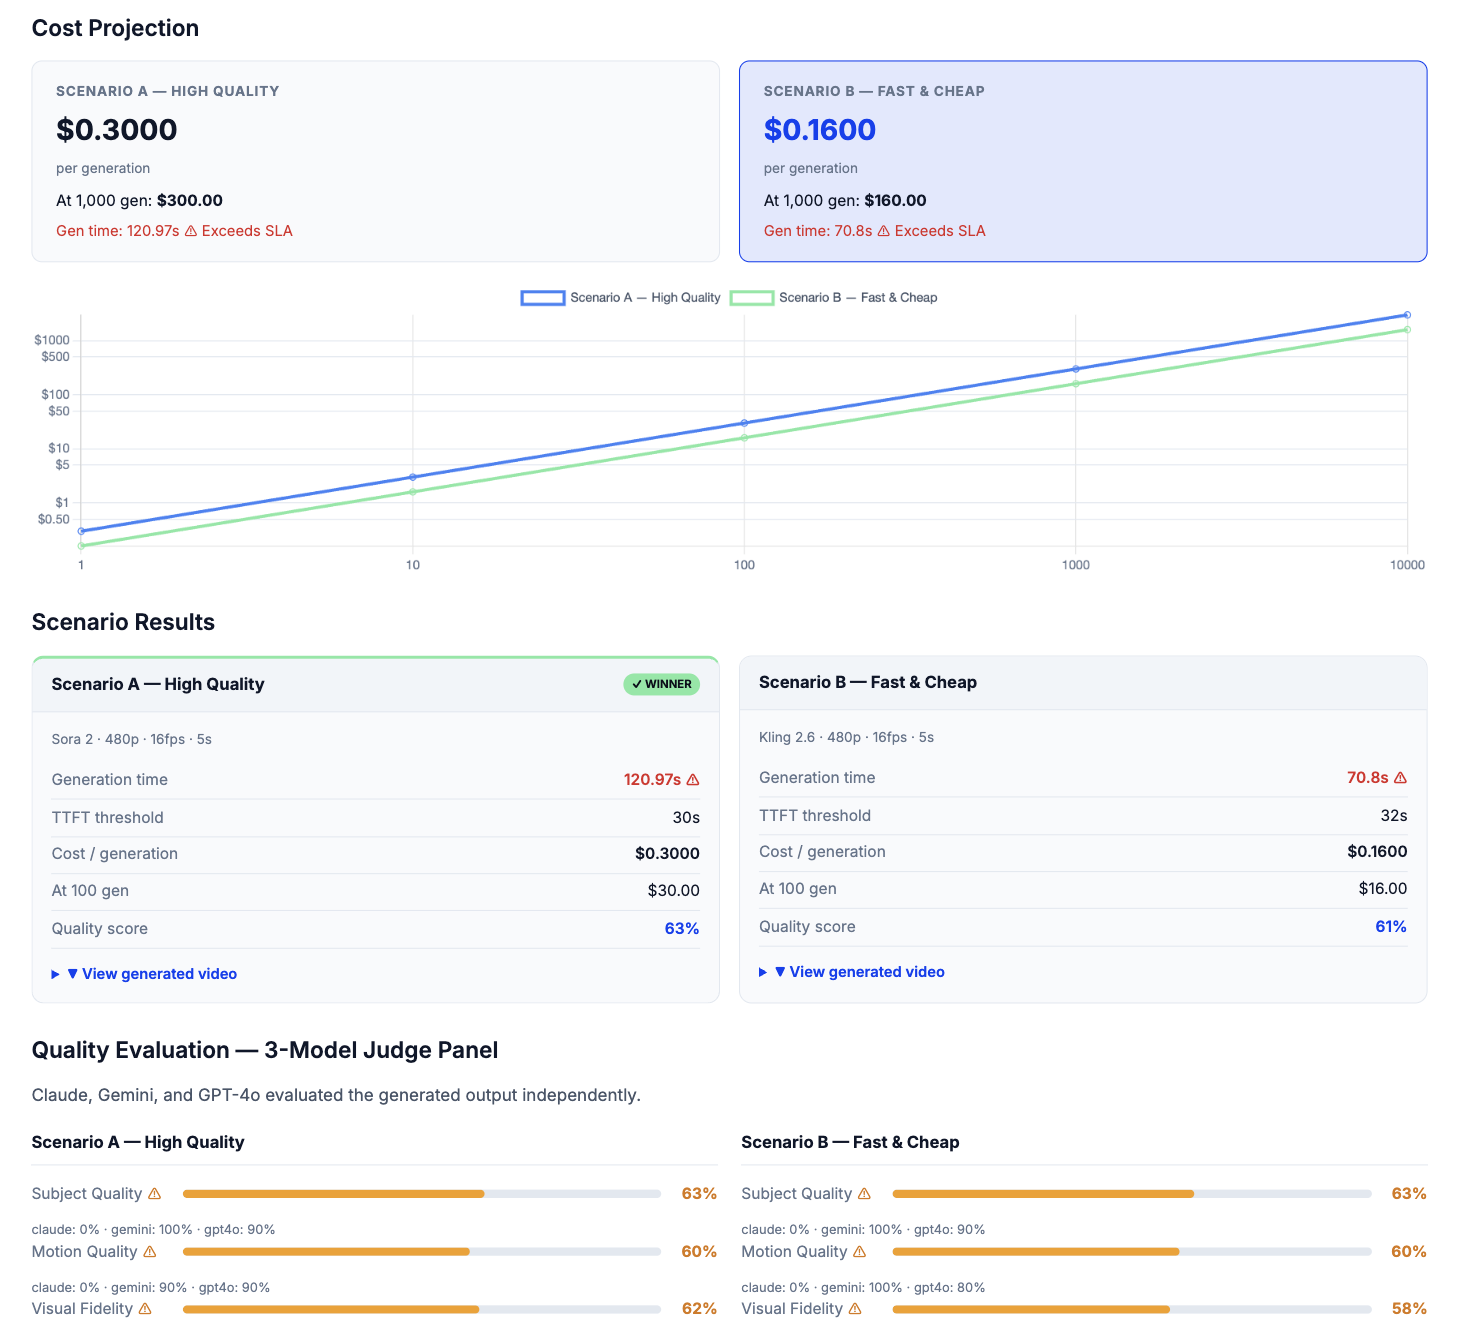
After running it, users get side-by-side generated videos, generation time, projected cost at scale, and quality scores from an independent 3-model judge panel.